Authorized attack simulation against the surfaces you nominate, run mostly by hand, written up so your engineers can reproduce and close every finding without a follow-up call.
Scanners are good at coverage and bad at consequence. They find the missing header and miss the fact that changing one integer in a request returns another customer's invoice. We run the tooling because it is careless not to, then spend the remaining days on access control, business logic, and chaining the small problems into one that matters.
Where a finding came out of a scanner, the report says so. You are paying for the judgement about what it means, not for the tool licence, and you should be able to see which is which.
Severity is not a feeling. If we rate something critical, the report shows you the account it reached.
Access control between roles, business logic abuse, injection, session handling, and file upload paths. Tested against OWASP WSTG with every role you issue us.
REST, GraphQL, and gRPC. Object and function level authorization, mass assignment, rate limiting, and what schema introspection leaks. OWASP API Top 10.
Android and iOS. Static review of the binary, local storage and keychain handling, pinning, tamper controls, and the backend the client talks to. OWASP MASVS.
Internet-facing services, patch levels, default and reused credentials, exposed admin interfaces, and the host nobody remembers provisioning. NIST SP 800-115.
Assumed breach from one workstation. Active Directory attack paths, credential reuse, privilege escalation, and segmentation that exists on the diagram only.
AWS, Azure, and GCP. IAM trust relationships and privilege escalation paths, public storage, key management, and the logging gaps that would hide an incident.
Manual reading of authentication, authorization, cryptography, and data handling paths, plus dependency risk and secrets committed anywhere in history.
One named objective, multiple vectors, fixed window, and an honest measurement of what your detection and response actually caught. Phishing only where scope allows.
Prompt injection through retrieved and user-supplied content, tool and function abuse, context-window exfiltration, and whether an agent can exceed its own authorization.
Asset list, rules of engagement, test window, named contacts, and the out-of-hours number. Signed.
Mapping what is actually there, which is routinely more than the asset list you gave us.
Manual exploitation. Anything critical is reported the day we find it, not held for the report.
Technical report and management summary, then a walkthrough call with the people who have to fix it.
We re-run the findings after your fixes and issue a closure letter stating what did and did not close.
Critical findings do not wait for the report. If we reach something that puts live data at risk, you get a call the same day with enough detail to act, and the written finding follows.
Every engagement opens a portal for your team. Findings appear as they are published rather than being held back for the report, and the retest is requested from the finding itself.
Each finding lands with its severity, its CVSS vector, its remediation state and the clock running. You start fixing in week one instead of waiting for a PDF.
Remediation is set by your team. Assessment is set by us, after review. They sit side by side on every finding so nobody has to guess whose move it is.
Resolved is greyed out for your team on purpose. Only a passing retest closes a finding, and only we can record it. It is the one place in the product where we deliberately took a button away.
Mark a finding fixed with a note and a build reference. The retest result posts against that round, so a finding that failed once keeps the history rather than quietly resetting.
Read it in the portal or download the PDF. A published report never changes; findings do. If something needs restating, a new version is issued and the old one stays readable.
Status moves, comments and downloads are written to an audit log you can export. That export is usually the next thing an auditor asks for.
Severity, CVSS, affected host, remediation state, retest result and the due date with time remaining. Filter by any of them, or switch to a board grouped by whatever your team works from.
The full CVSS vector, affected component, evidence, and the activity trail underneath. The sidebar states plainly which status is yours to set and which is ours.
Assets are the warp, findings are the threads. A dashed thread is still open, a solid one is fixed and verified, a thin grey one was accepted. The work is finished when every thread is woven in.
Every report with its version history. Published versions are immutable, so the document your auditor reads in March is the document we issued in October.
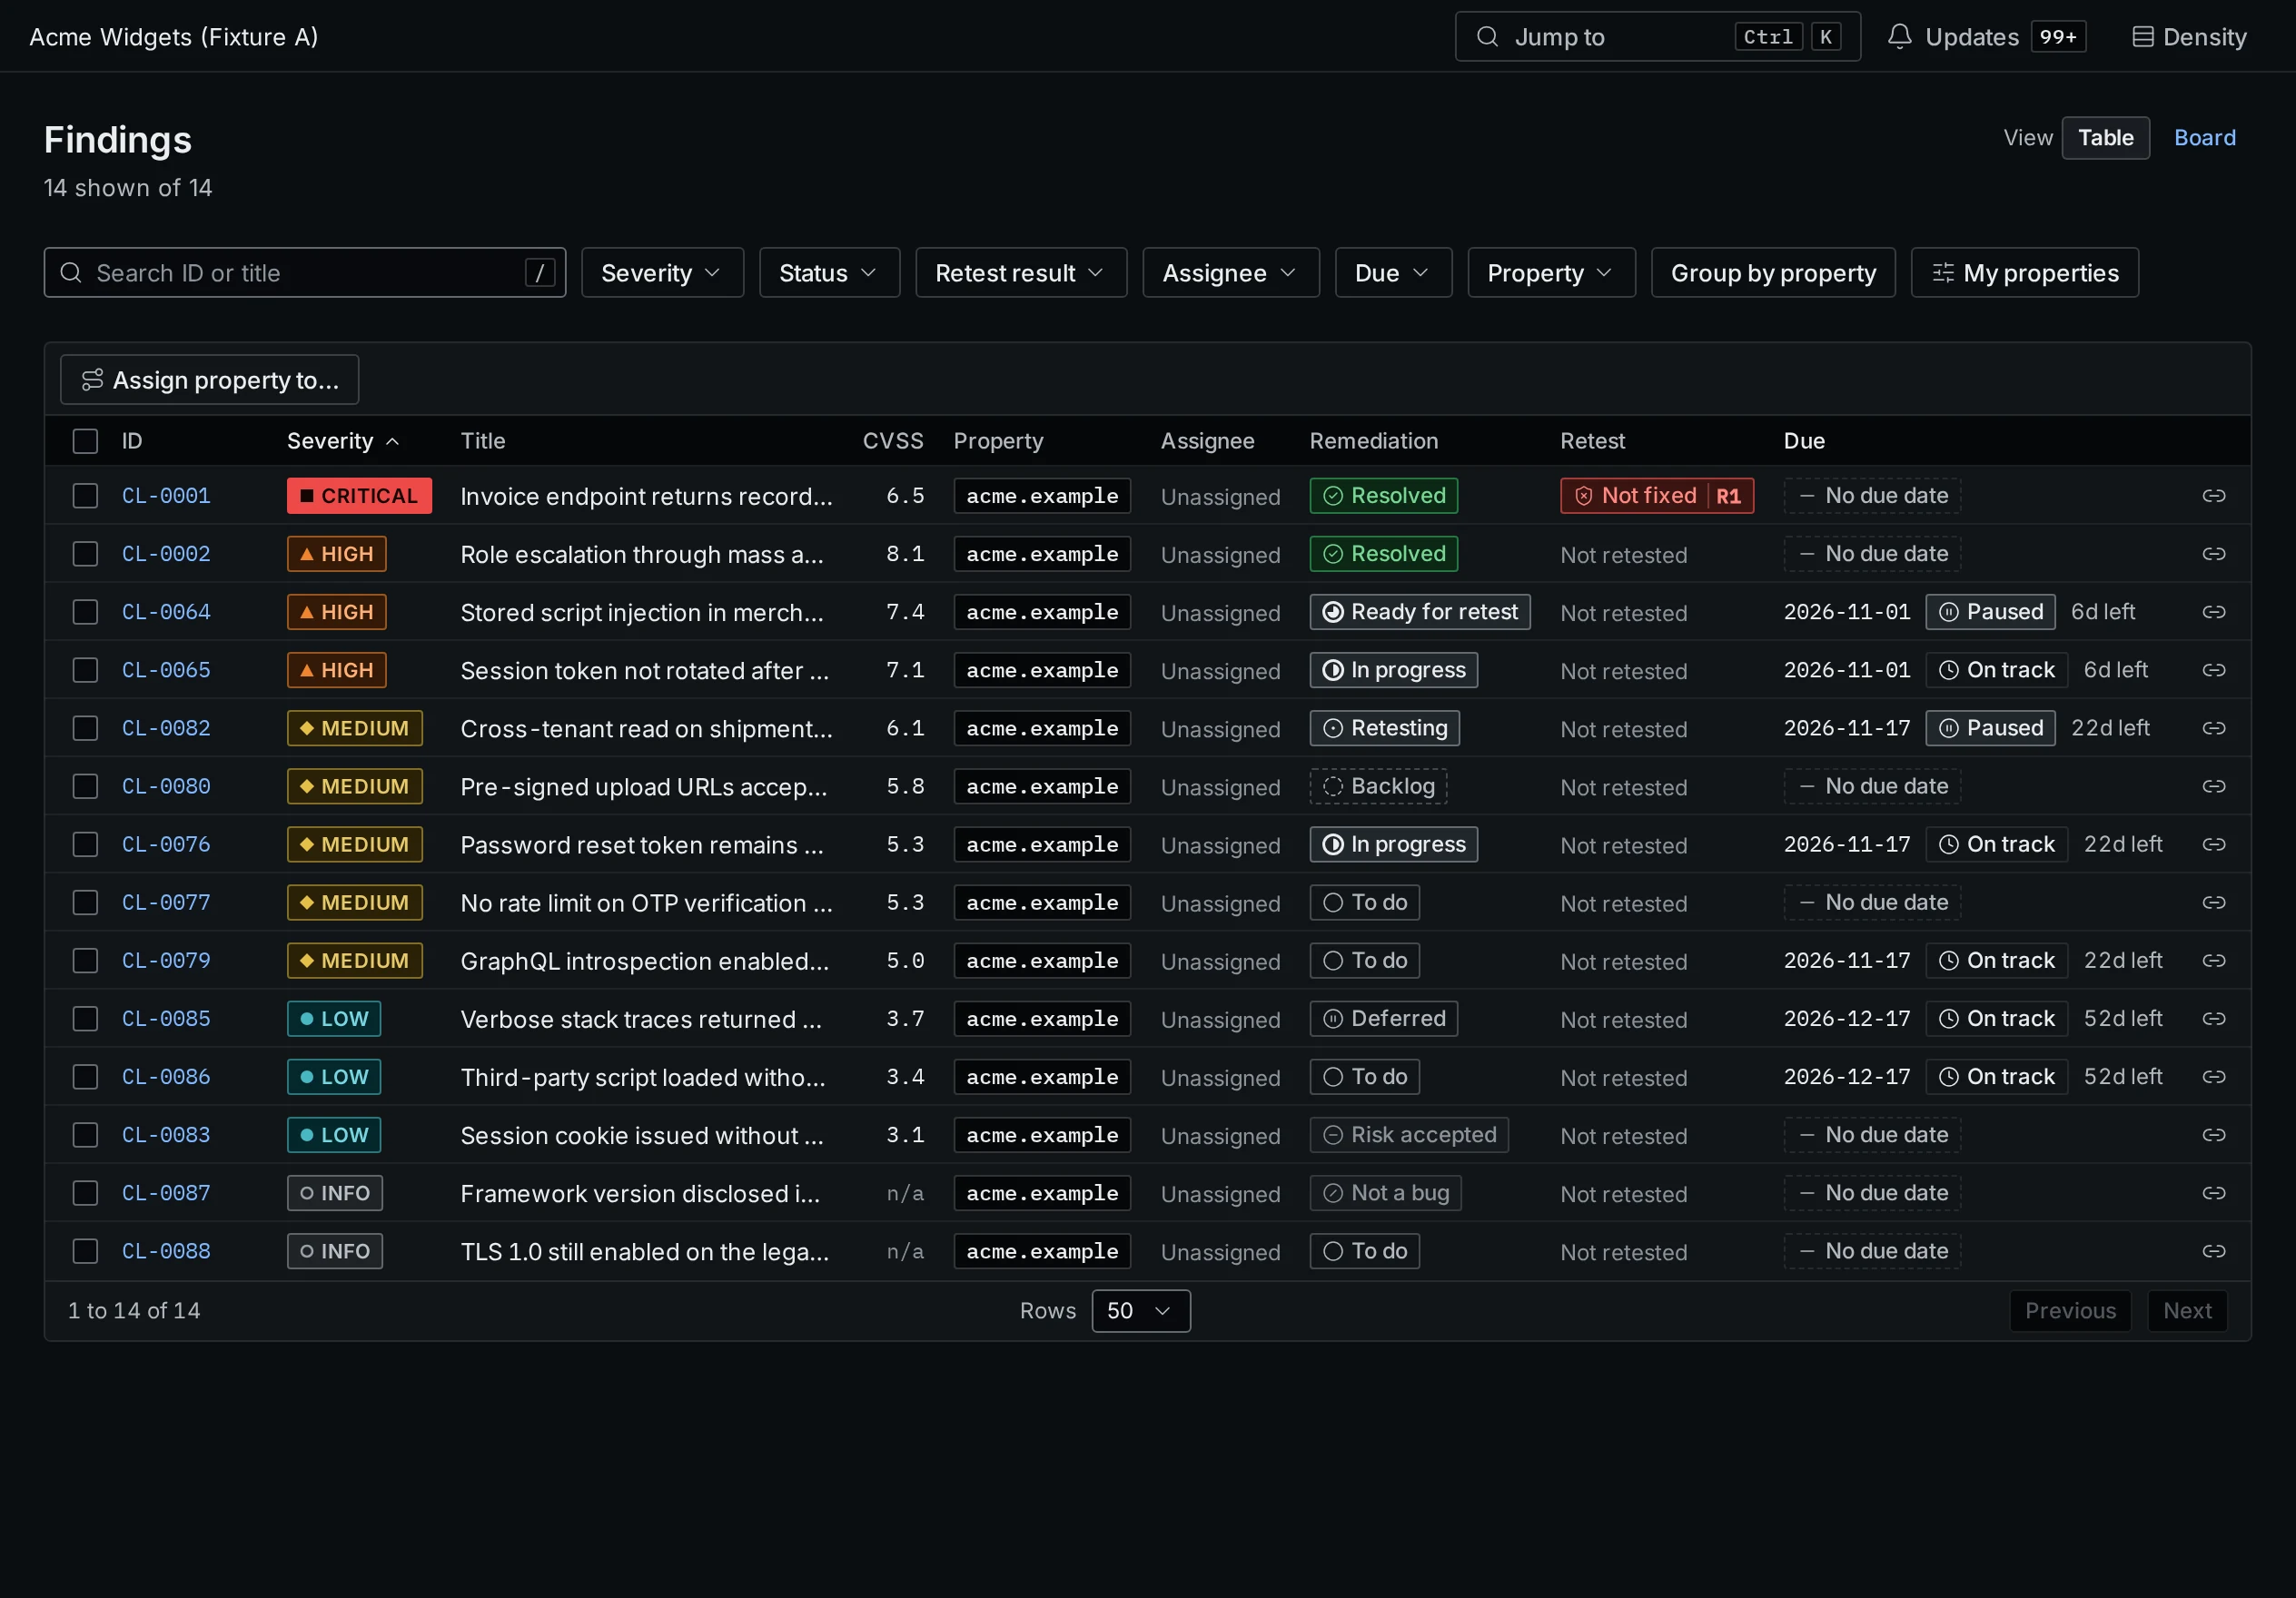
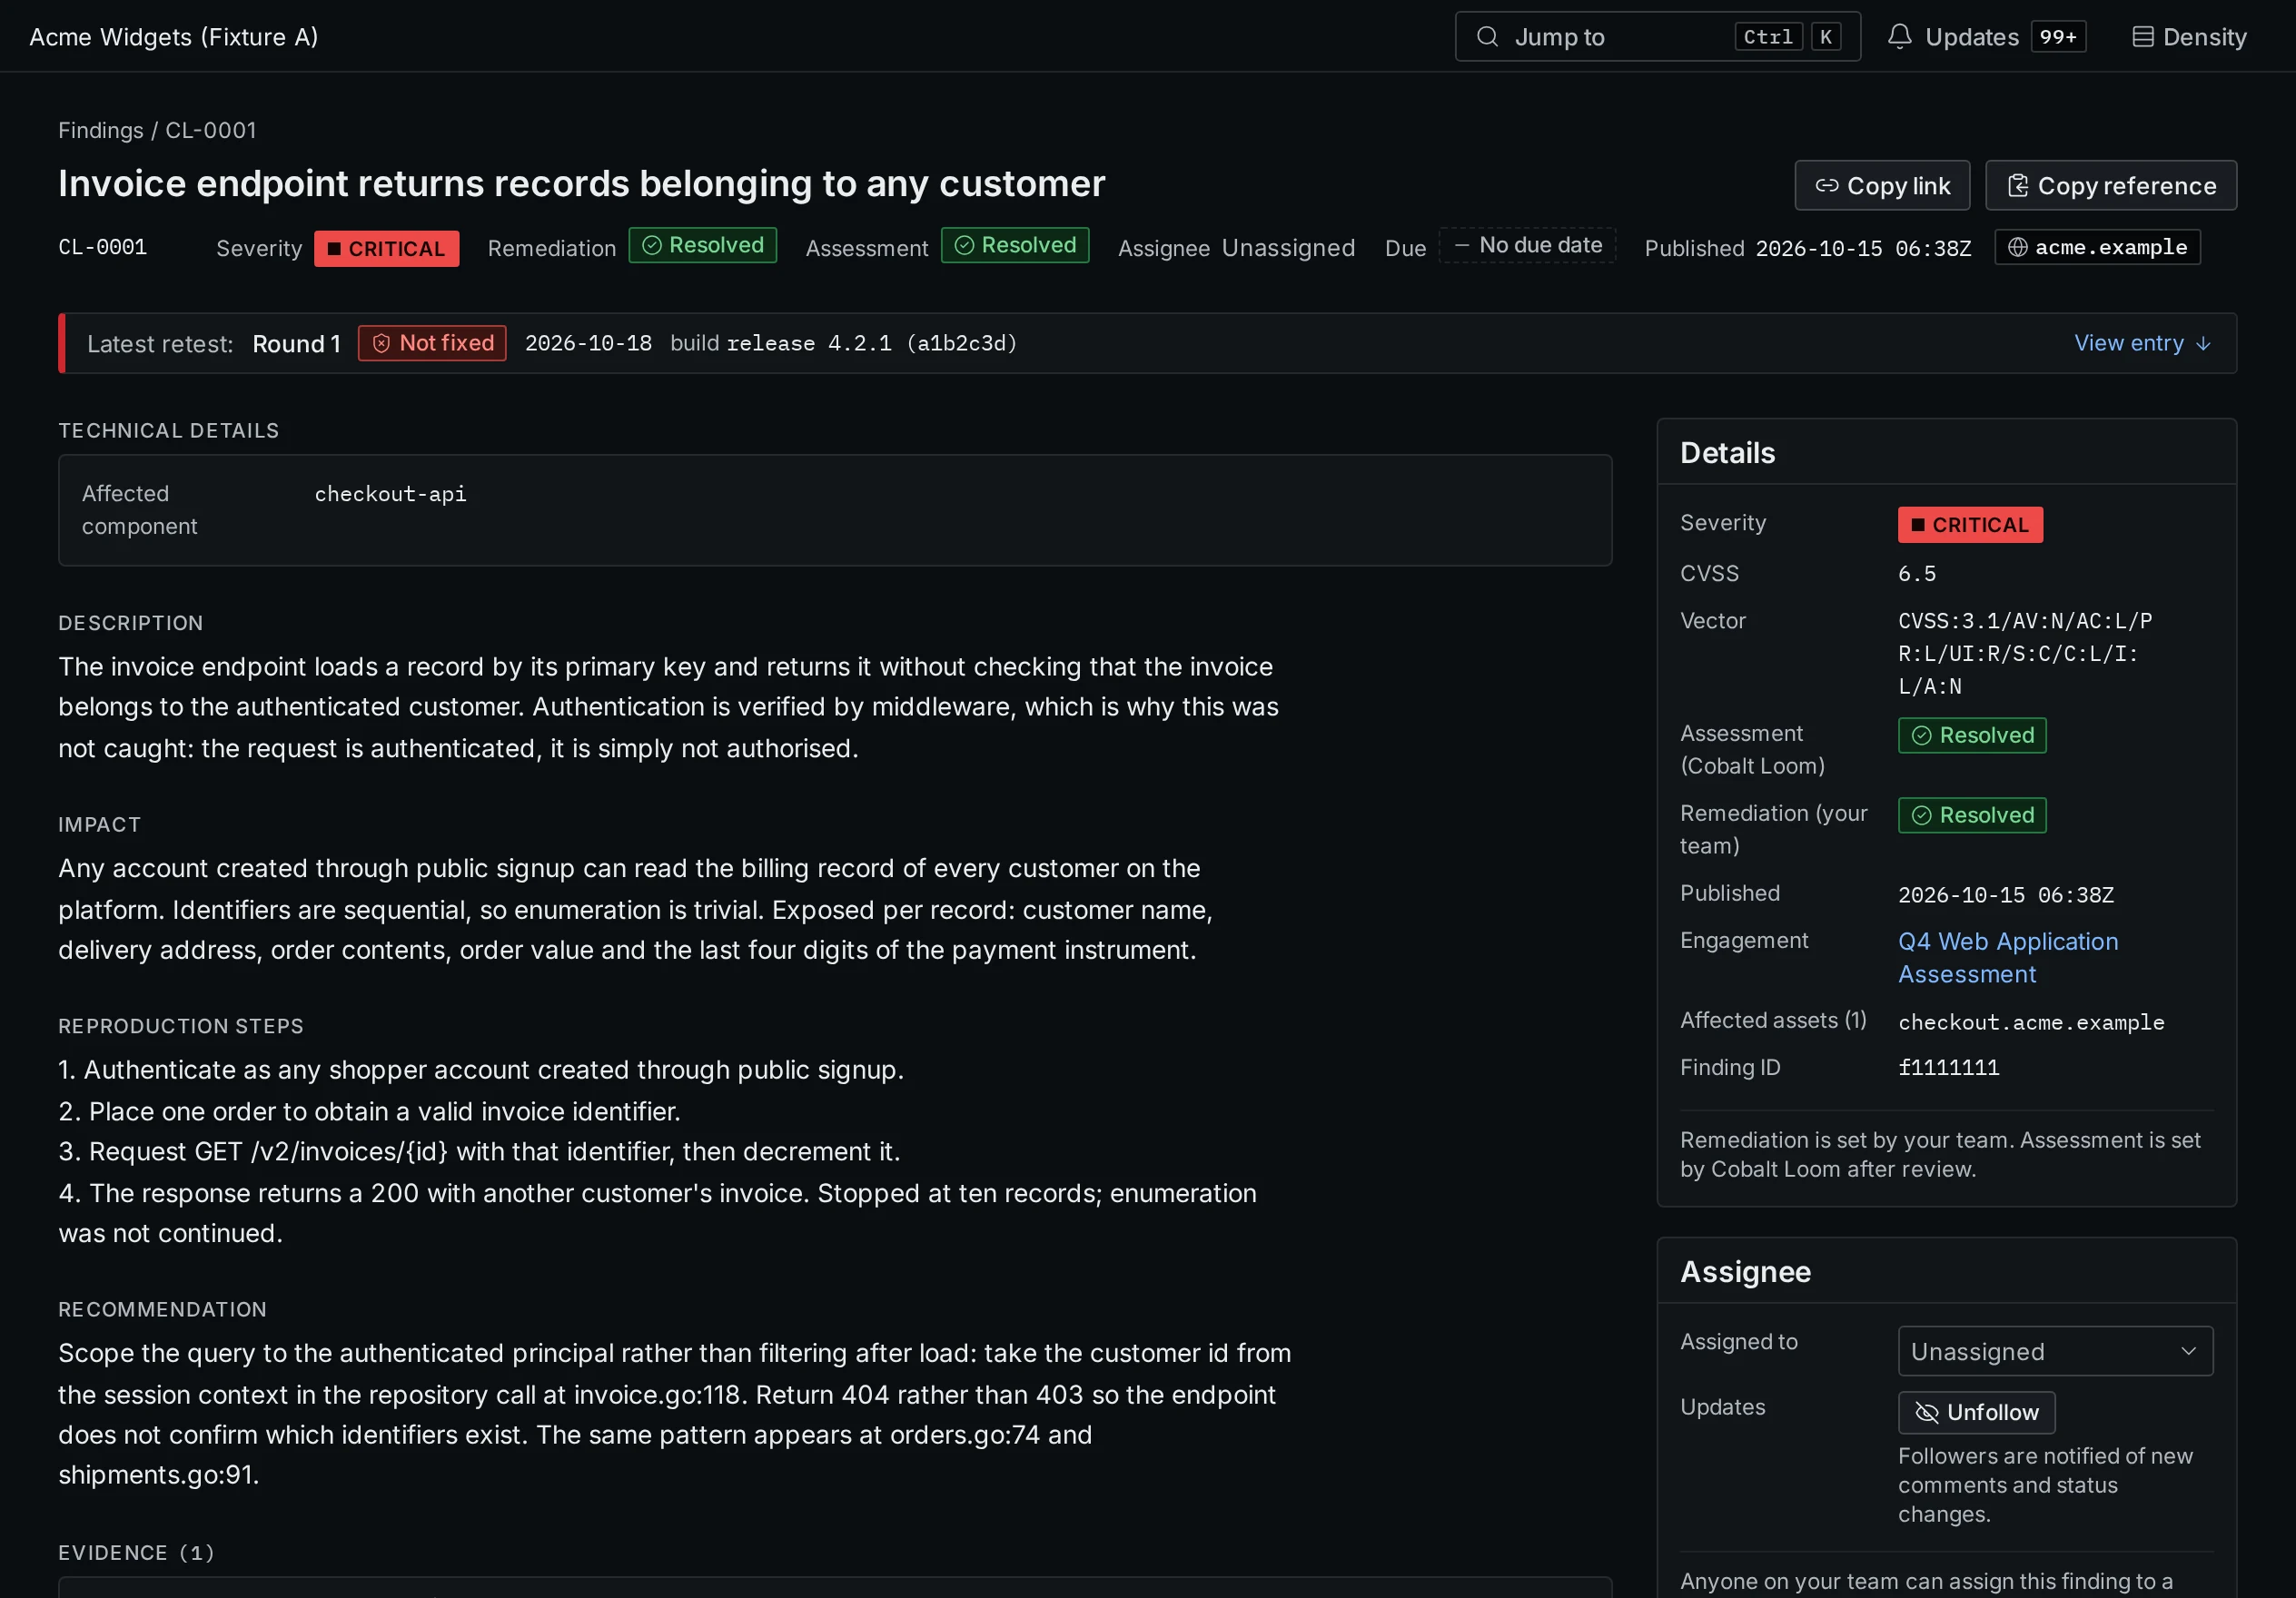
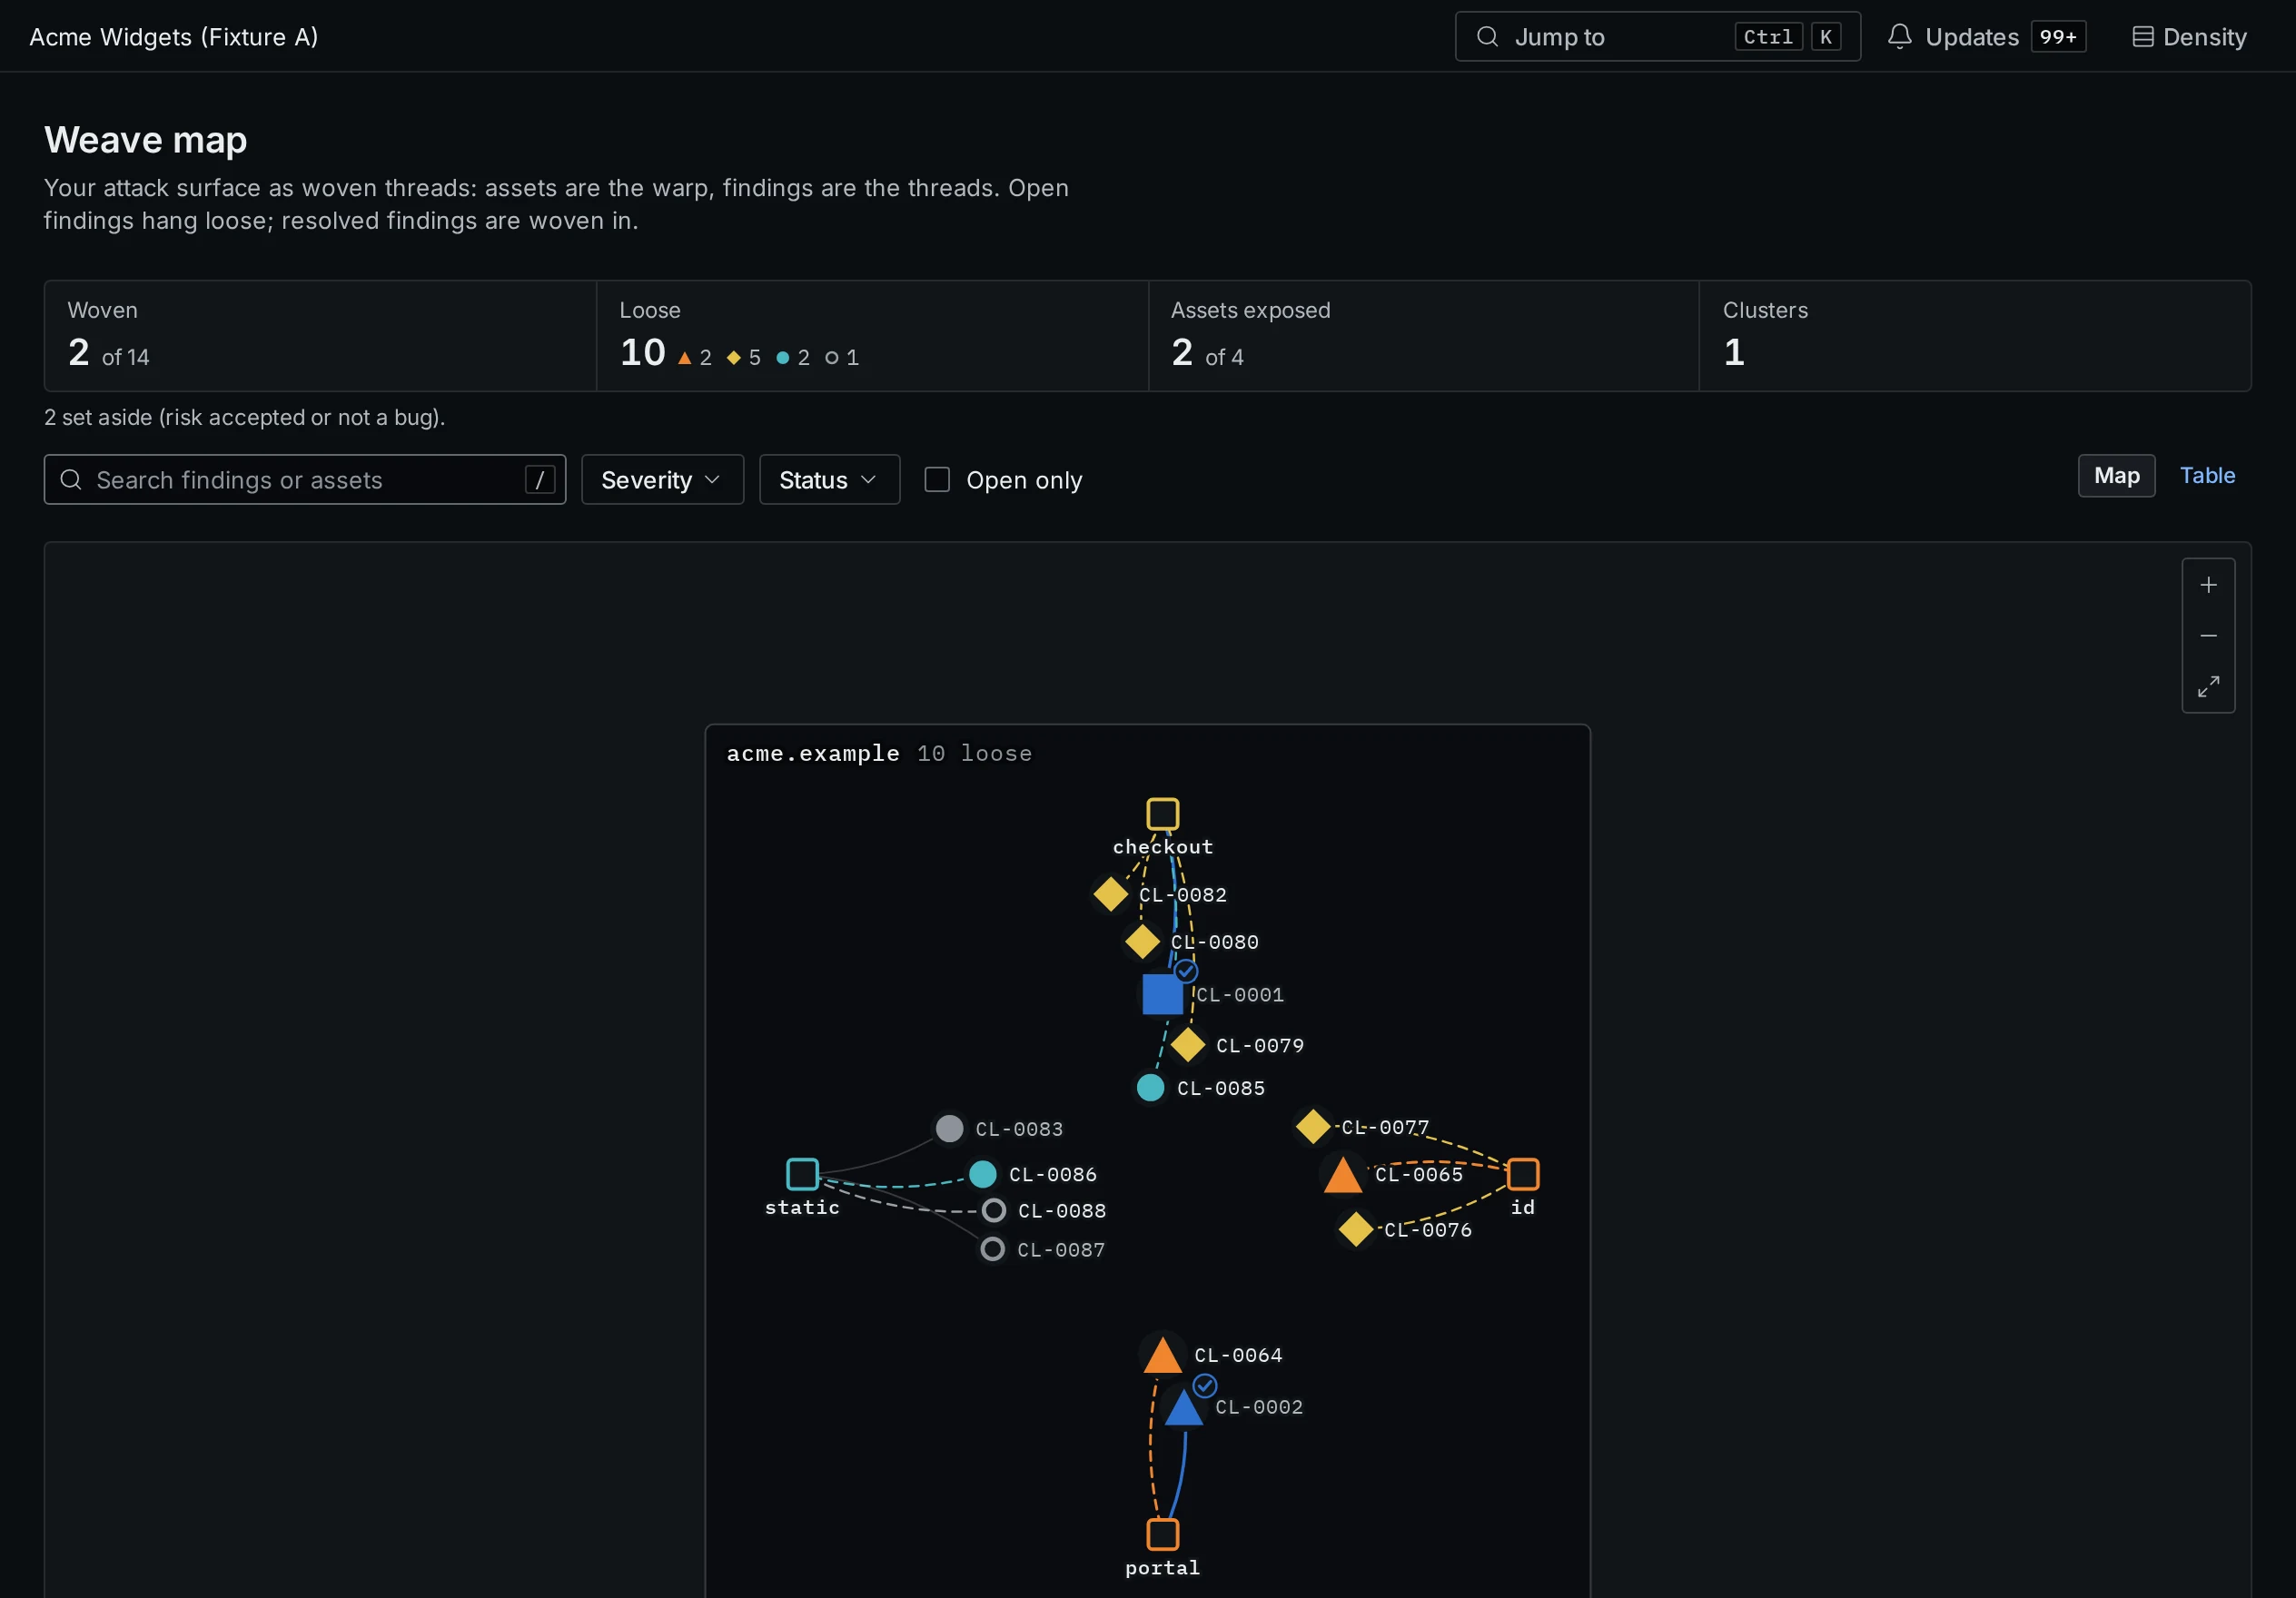
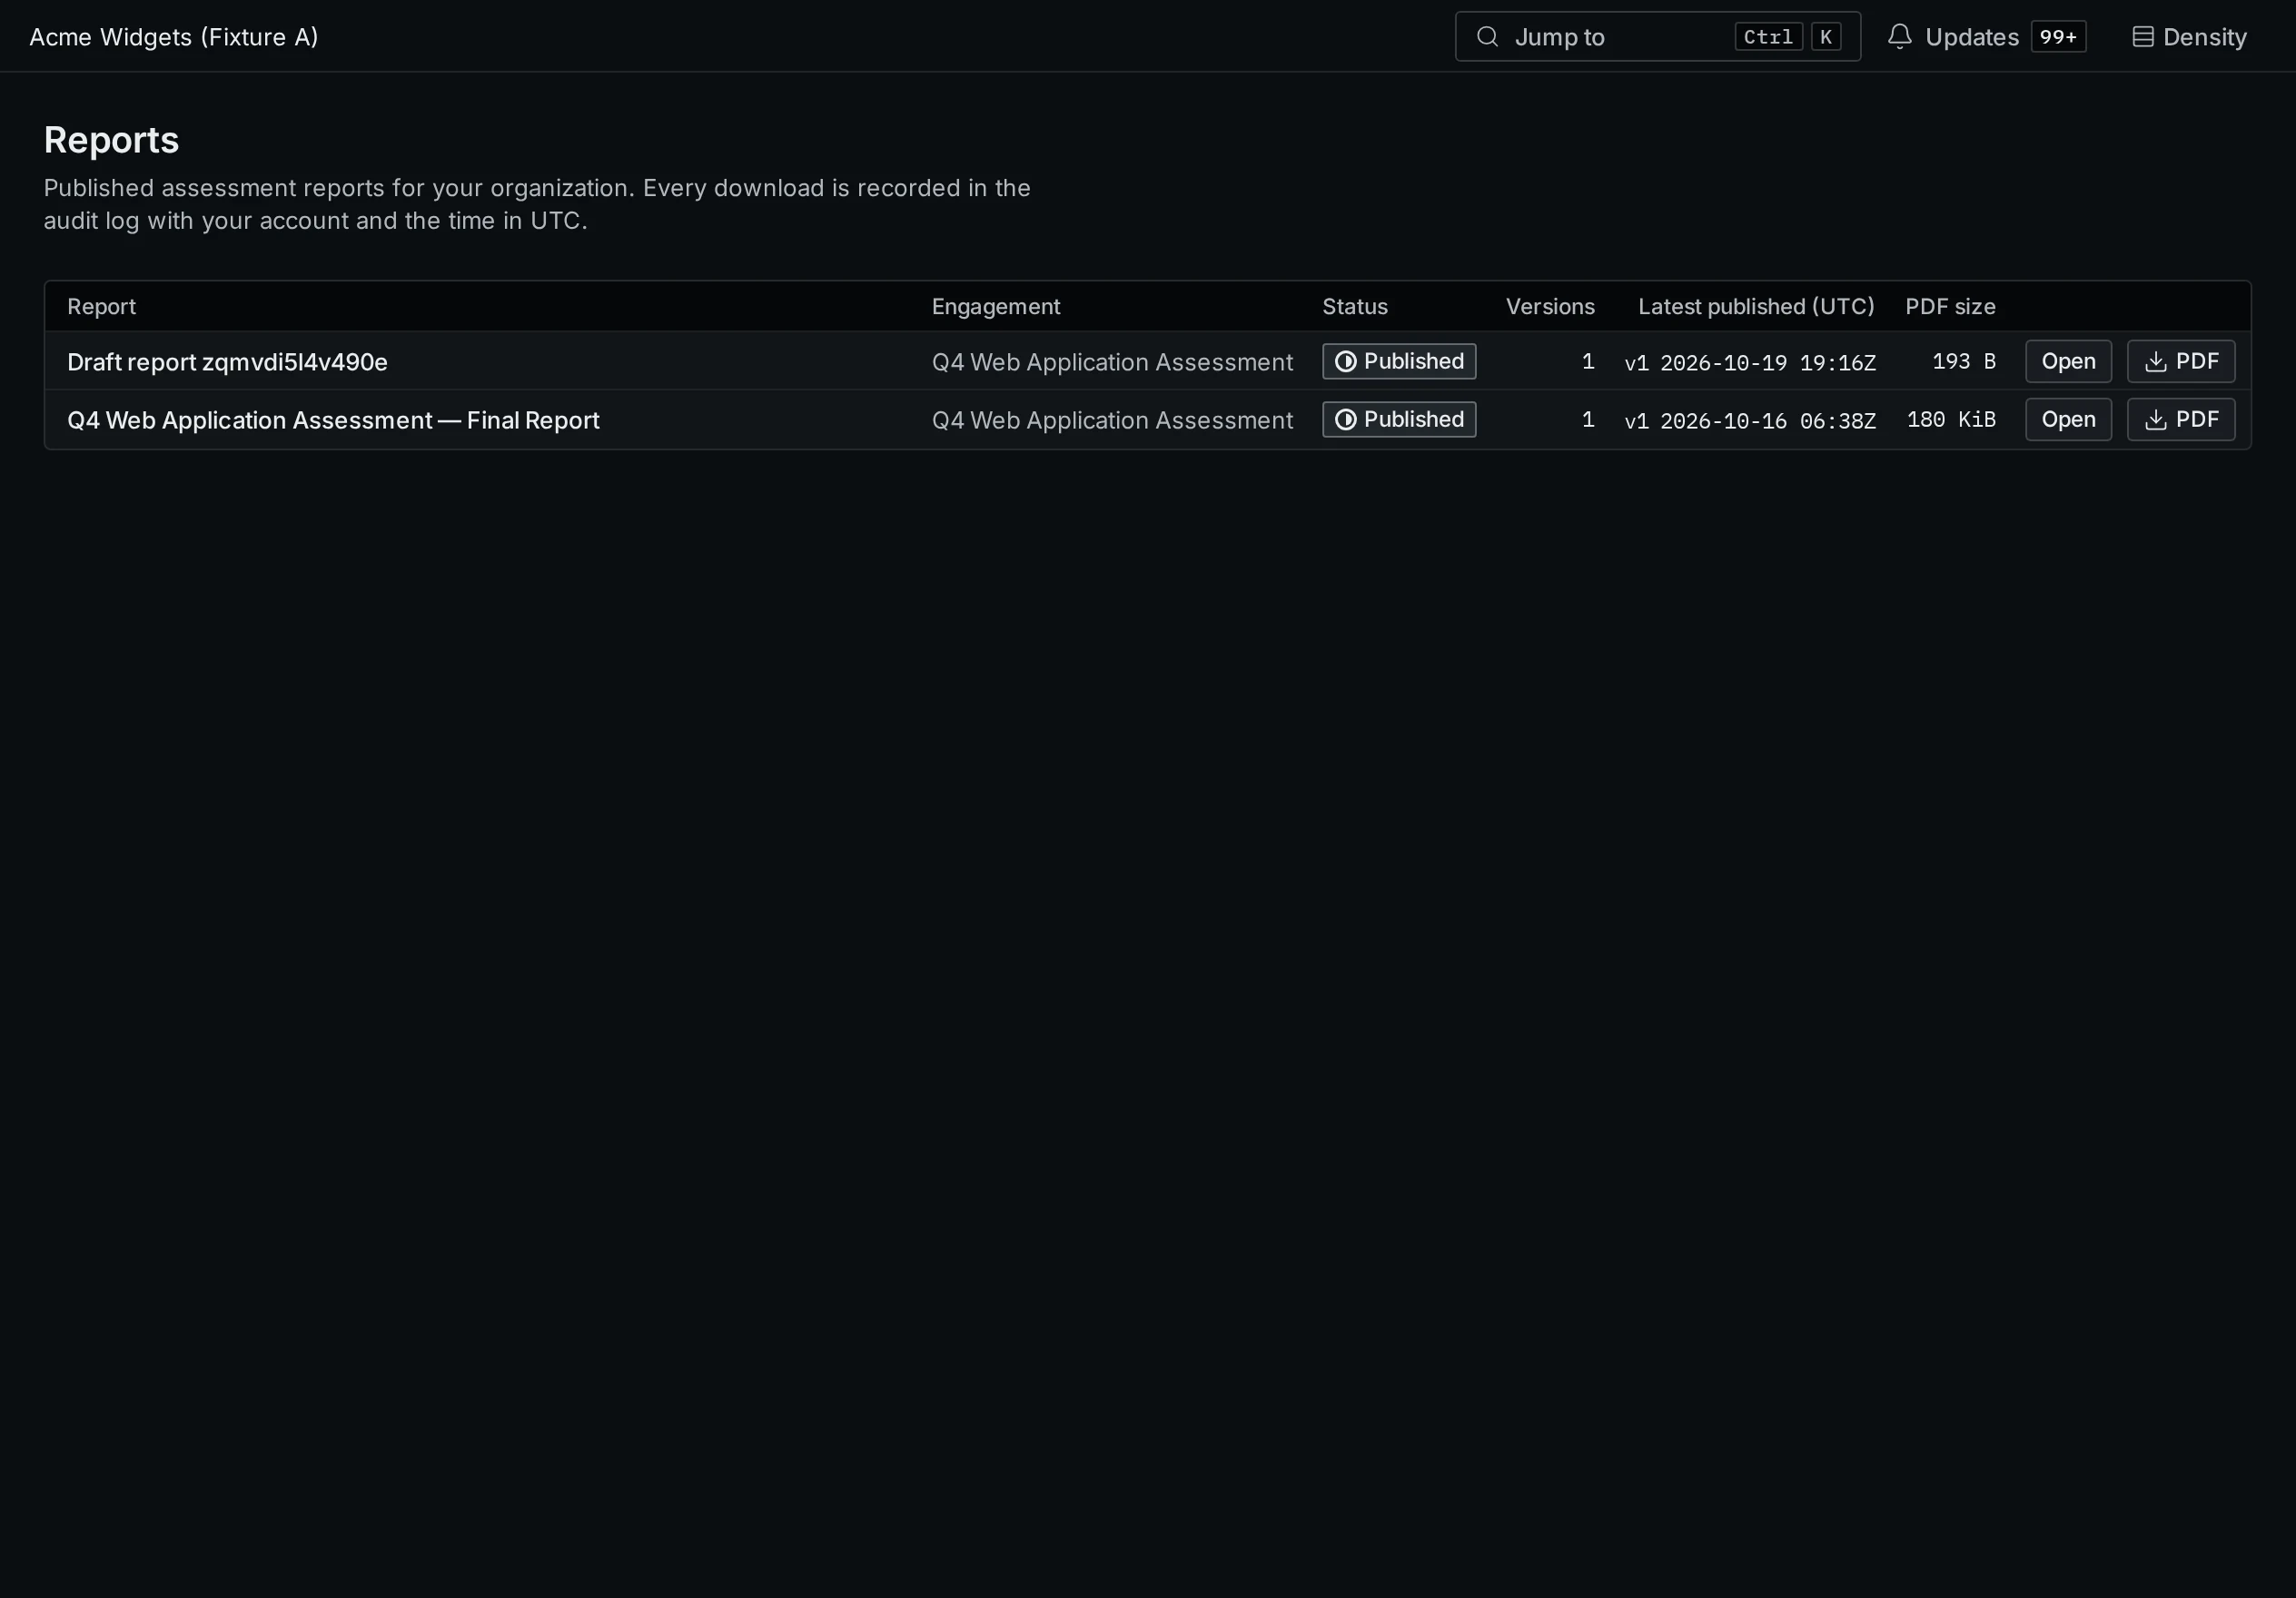
Screens are from the live product, populated with a fictional client. No real engagement data appears on this site.
Every finding carries a CVSS 3.1 base score, because that is the number your auditor and your insurer expect to see. It is also a score calculated without knowing anything about your business.
So we print a second rating alongside it, and when the two disagree we explain the gap in the finding itself. A medium that exposes your entire customer table is not a medium in your environment. A high on an internal service that three people can reach, behind a VPN, on a host scheduled for decommission, is not worth your weekend.
One account for every permission level. Most access-control findings are impossible to reach without them.
Someone who can answer a question during the window and unblock an environment the same day.
Staging with empty tables and stubbed payments tests the staging environment, not your product.
These are in the scope document too. Putting them on the website first saves everyone a meeting.
Signed scope, named contacts on both sides, an agreed window, and a number that reaches a human at two in the morning. All four, or nothing starts.
We will tell you where your availability looks fragile. We will not prove it on a production system without a separate written instruction and a window you have chosen.
Automated results are labelled as automated. If an engagement was mostly tooling because that is what the scope allowed, the report says that plainly.
If the test comes back quiet, you get a quiet report listing the surfaces covered and the depth reached. That is a result you can hand an auditor.
Grey-box is usually the right answer. Black-box spends your budget on reconnaissance that a real attacker would happily spend months on for free, and you are paying by the day. Given source and working accounts, the same budget goes into exploitation and you get more findings that matter. We will run black-box where you need to measure what an outsider reaches, and we will say which one the scope document reflects.
We stop at proof and describe the rest. If demonstrating impact would mean destroying data, moving money, or reading records belonging to a real person, we document the point we reached, explain what would follow and why we did not continue, and leave the decision about a controlled demonstration to you.
The findings from the original report, re-run against the same scope after your fixes. It is not a fresh test, and it will not catch something introduced in the meantime by a feature that shipped last week. The closure letter lists what closed, what did not, and what you accepted as business risk.
Yes. The management summary exists for exactly that, and we will join a call with your auditor to walk through method and coverage. We will not write a one-page attestation that strips out the findings and keeps only the letterhead.
Tell us and we will look again. If your compensating control genuinely closes it, the finding is downgraded or withdrawn and the report records why. If it does not, the finding stays and your disagreement is recorded alongside it. Both of those are better than quietly deleting it.

 CobaltLoom